
Introduction
Supervised learning is an important part of artificial intelligence and machine learning. It helps computers learn from examples instead of relying only on manually written instructions. This approach uses labeled data to understand patterns and relationships between different variables. It is widely used in healthcare, finance, education, marketing, and many other industries. Understanding supervised learning can help us see how intelligent systems make useful predictions.
1. What Is Supervised Learning?
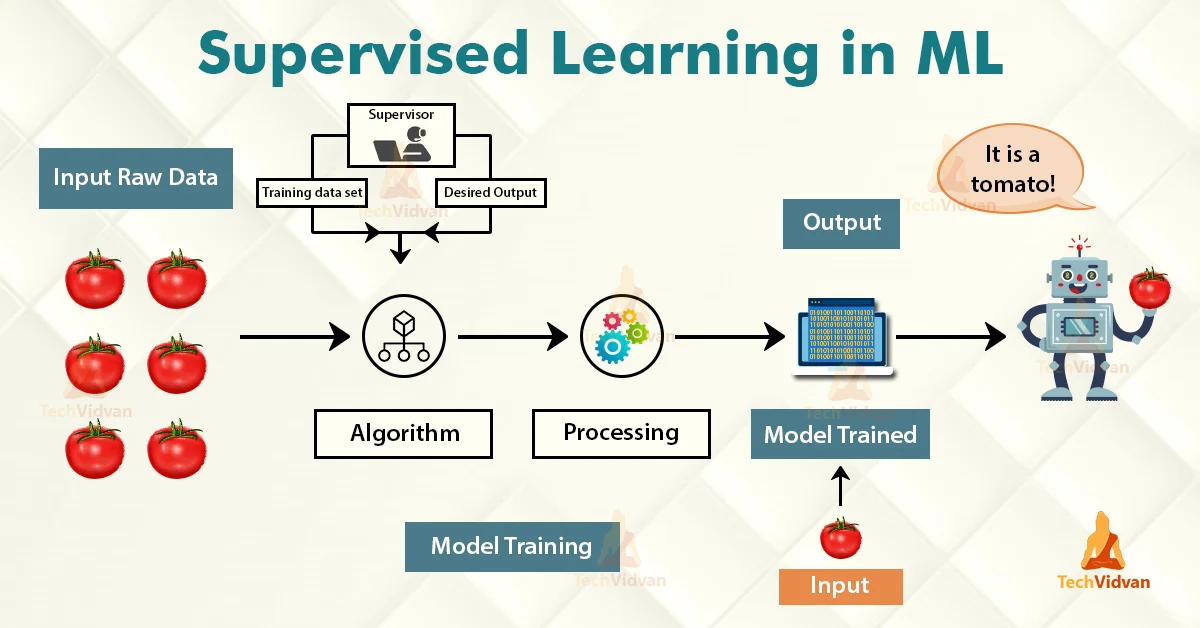
Supervised learning is a machine learning technique in which a model learns from labeled examples. Each training example contains input information and a corresponding correct output. The model studies these examples to identify meaningful patterns within the available data. During training, it compares its predictions with the expected answers. This comparison helps the model adjust its internal parameters and improve its performance. After learning, the model can make predictions about new data it has never encountered. For example, it can estimate house prices using information about location and size. The main goal is to produce accurate and reliable predictions from real-world information.
2. How Supervised Learning Works
The supervised learning process begins with collecting relevant data from suitable sources. The collected information is organized and labeled according to the problem being solved. Next, the data is cleaned to remove errors, inconsistencies, and unnecessary information. The dataset is usually divided into training, validation, and testing portions. The training data teaches the model to recognize patterns and relationships. Validation data can help select suitable settings and identify potential overfitting. Testing data evaluates how well the trained model performs on unseen examples. Finally, the model can be deployed to make predictions on new input data.
3. Types of Supervised Learning
Supervised learning is generally divided into two major categories: classification and regression. Classification predicts a category or class based on the information provided. For example, an email classifier determines whether a message is spam or legitimate. Regression predicts a numerical value that can vary across a continuous range. A common example is estimating a property’s price using its size and location. Both approaches learn from labeled examples, but their predicted outputs are different. The choice between them depends on the objective and the type of target variable. Selecting the appropriate method is an important step toward building an effective model.
4. Classification in Supervised Learning
Classification is used when the desired output belongs to a specific group or category. It helps computers distinguish between different classes using patterns in labeled training data. A medical classification model may help identify patients who need additional screening. Banks can use classification systems to flag potentially fraudulent financial transactions. Businesses may also classify customer feedback as positive, negative, or neutral. Popular classification algorithms include decision trees, logistic regression, and support vector machines. Model performance can be measured through accuracy, precision, recall, and the F1-score. These measurements help determine whether the model is suitable for its intended application.
5. Regression in Supervised Learning
Regression focuses on predicting numerical values rather than assigning predefined categories. It examines how input variables relate to a continuous target variable. For instance, a company may estimate future sales using historical sales records. Weather-related applications can use regression to estimate temperatures or other numerical measurements. Linear regression is one of the most familiar algorithms used for this purpose. More advanced methods can capture complex relationships within large and varied datasets. Common evaluation metrics include mean absolute error and root mean squared error. A well-trained regression model can support planning, forecasting, and informed decision-making.
6. Common Supervised Learning Algorithms
Several algorithms are available for solving supervised learning problems. Linear regression is commonly used to predict continuous numerical outcomes. Logistic regression is frequently applied to classification tasks involving class probabilities. Decision trees make predictions through a sequence of feature-based decisions. Random forests combine multiple decision trees to improve predictive performance and stability. Support vector machines can separate classes or estimate relationships in suitable feature spaces. Neural networks can learn complex patterns when sufficient data and computing resources are available. The best algorithm depends on the dataset, problem requirements, interpretability, and available resources.
7. Importance of Training Data
Training data plays a central role in the success of supervised learning. The model can only learn useful patterns when the examples contain relevant information. Accurate labels help it understand which outputs correspond to particular inputs. Incomplete, outdated, or incorrectly labeled records can reduce prediction quality. A dataset should represent the conditions in which the model will eventually be used. Researchers also need to consider possible bias in the collected information. Data preparation may involve removing duplicates, handling missing values, and scaling numerical features. High-quality data creates a stronger foundation for developing dependable machine learning systems.
8. Applications in Healthcare
Supervised learning has several useful applications in modern healthcare. Models can analyze medical images to identify patterns that deserve professional attention. They can also estimate health risks using suitable patient records and clinical measurements. Hospitals may use predictive models to support resource planning and patient management. Researchers can apply these methods to study relationships within medical datasets. However, healthcare predictions must be evaluated carefully before they influence clinical decisions. Patient privacy, data quality, and fairness are important considerations throughout development. Supervised learning should support qualified healthcare professionals rather than replace their judgment.
9. Applications in Business and Finance
Businesses use supervised learning to understand customers and improve operational decisions. Retailers can predict product demand using previous sales and relevant market information. Financial institutions may classify suspicious transactions to help detect possible fraud. Companies can estimate customer churn and identify groups that may need additional support. Credit risk models can help evaluate applications using appropriate financial information. Marketing teams may predict which customers are more likely to respond to particular offers. These applications can improve efficiency when models are properly tested and monitored. Organizations must still protect personal information and check predictions for unfair outcomes.
10. Advantages of Supervised Learning
One major advantage of supervised learning is its ability to make measurable predictions. Because the training data contains known answers, model performance can be evaluated systematically. This makes it easier to compare different algorithms and improve their settings. Supervised learning can automate repetitive tasks that would otherwise require substantial manual effort. It can also uncover relationships that may be difficult to notice through simple observation. Once deployed, a suitable model can process new examples quickly and consistently. Its methods can be applied to many fields, from agriculture to online services. These benefits make supervised learning a valuable tool for data-driven problem-solving.
11. Challenges and Limitations
Despite its advantages, supervised learning has several limitations that should not be ignored. Preparing large amounts of accurately labeled data can require significant time and effort. Models may perform poorly when they encounter situations unlike those in their training data. Overfitting occurs when a model learns training examples too closely and struggles with new ones. Biased training data can produce predictions that disadvantage certain individuals or groups. Some complex models are also difficult to interpret or explain clearly. Changes in real-world conditions may gradually reduce a model’s predictive accuracy. Regular testing, monitoring, and careful data management help reduce these risks.
12. Supervised Learning and the Future
Supervised learning continues to contribute to the development of practical artificial intelligence systems. Improvements in data collection and computing power are expanding its possible applications. Researchers are exploring better ways to train models with less labeling effort. Combining supervised learning with other machine learning approaches can solve more complex problems. Businesses are increasingly interested in reliable predictions that support everyday decisions. Future systems will need stronger protections for privacy, fairness, and data security. Human oversight will remain important when predictions affect important personal or professional outcomes. With responsible development, supervised learning can continue to provide meaningful value across industries.
Conclusion
Supervised learning enables computers to learn from examples with known outputs. It supports classification, regression, forecasting, and many other predictive tasks. Its effectiveness depends on suitable algorithms, representative data, and careful evaluation. Although challenges such as bias and overfitting remain, they can be managed through responsible practices. Overall, supervised learning is a fundamental technology for building useful and reliable intelligent systems.
Frequently Asked Questions (FAQs)
1. What is supervised learning in simple words?
Supervised learning is a machine learning method in which a computer learns from examples that already contain the correct answers. It uses these examples to make predictions about new information.
2. What are the main types of supervised learning?
The two main types are classification and regression. Classification predicts categories, such as spam or non-spam, while regression predicts numerical values, such as house prices or sales figures.
3. Where is supervised learning used in real life?
Supervised learning is used in healthcare, banking, online shopping, email filtering, fraud detection, sales forecasting, and customer analysis. Its purpose is to make predictions that help people and organizations make better-informed decisions.